Newsletter

Teardown Engineering and Evaluation Lab

From product to transistor.

We deliver actionable insights and technical detail a client can act on: where a competitor leads and trails, how they innovate, what it cost them, and which claims hold up under the microscope.

The most advanced chips in the world are analyzed here, in full teardowns from product to package and package to transistor, by a team experienced in systems, architecture, fab, and lab.

To discuss teardown access, subscriptions, or a commissioned teardown, contact the sales team.

Top-down photograph of a Huawei Ascend 910C accelerator card with two large dies at its centre and rows of components around them Opened Apple M5 Max package showing a blue logic die between four memory stacks, with epoxy residue around the edges Two-dimensional X-ray through a ball-grid-array package, bright solder balls in rings around the die area with a one millimetre scale bar Annotated die shot of the Intel Panther Lake compute tile with every block outlined and labelled Colour elemental map of NMOS and PMOS gate-all-around transistor stacks between two nano-TSVs, with a 20 nanometre scale bar
Huawei Ascend 910C accelerator card Optical, full card

The lab in two minutes.

Andrew Wagner on what the lab takes apart, how far down it can see, and what clients get.

What a teardown delivers.

Answers and insights, four examples with the lab’s own figures and measurements.

01

Floorplan and architecture analysis

Full-die imaging after custom delayering, block identification and area measurement, generation-over-generation and cross-foundry comparison

Die shots of devices that defeat conventional delayering, including the first products with backside power delivery, with every block identified, measured, and compared with its predecessor and with other foundries’ nodes.

What it reveals: Die and block areas, core counts, cache sizes and densities, where the node’s density gain went, and what the silicon costs.

Annotated Intel Panther Lake compute tile floorplan
Intel Panther Lake compute tile on 18A, annotated, with block areas compared against Lunar Lake

Panther Lake vs Lunar Lake block areas from the floorplan

Intel 18A compute tile against its TSMC N3B predecessor

Block Change Note
P-core (Cougar Cove) ~0% L2 2.5 → 3 MiB in the same area
Shared P-core L3 −14.8%
LP E-core cluster (Darkmont) −5.0% 1.5 MiB L2 region −14.9%
NPU (NPU 5 vs NPU 4) −36.9% Same INT8 MACs, 6 scratchpads vs 12
NCE envelope +22.6% 3 engines vs 6, larger MAC arrays
GPU L1/SLM +5% 192 → 256 KiB, density +27%

Source: STEEL Panther Lake teardown, September 2026

Annotated HiSilicon Kirin 9030 floorplan
HiSilicon Kirin 9030 on SMIC N+3, annotated, with block-area changes from the Kirin 9020

Kirin 9030 vs Kirin 9020 block areas from the floorplan

SMIC N+3 against N+2, same ~140 mm² die

Block Change Note
Prime core (TaiShan) −7.6% L2 1 → 2 MiB; −21% excluding L2
Middle core −22% 3 → 4 cores
Big CPU cluster ~0% L3 10 → 12 MiB
Tiny CPU cluster slightly larger Shared L2 2 → 4 MiB
GPU compute unit −28% Ray tracing added; 4 → 6 CUs
GPU cluster +~10% Non-CU area +33%
NPU 1 Lite + 2 Tiny From 1 Lite + 1 Tiny

Source: STEEL SMIC N+3 teardown, June 2026

Annotated HiSilicon Kirin 9030 floorplan
Cache array sizes and achieved densities read directly off the Kirin 9030 die shot

Cache arrays measured on the die shot Kirin 9030

Achieved density of SRAM arrays as placed, against the previous generation

Array Area Achieved density
SLC, 128 KiB 0.0392 mm² 25.5 Mib/mm²
SLC array vs Kirin 9020 −18% 0.0477 → 0.0392 mm²
L3, 64 KiB 0.0210 mm² 23.8 Mib/mm²
Prime-core L2, 32 KiB 0.0142 mm² 17.6 Mib/mm²
L2 array vs Kirin 9020 −17% 0.0171 → 0.0142 mm²
SLC capacity 3 MiB per bank From 2 MiB, 24 arrays vs 16

Source: STEEL SMIC N+3 teardown, June 2026

Annotated Panther Lake GT1 GPU tile floorplan Annotated Panther Lake GT2 GPU tile floorplan
Panther Lake GT1 (Intel 3, top) and GT2 (TSMC N3E, bottom) GPU tiles, annotated, with core and cache areas compared

Xe3 across two foundries GPU tile areas

Panther Lake GT1 (Intel 3) and GT2 (TSMC N3E) against Lunar Lake Xe2

Metric GT1, Intel 3 GT2, TSMC N3E
Xe cores 4 12
Xe core area vs Lunar Lake +~69% GT1 is ~55% larger than GT2
L2 capacity 4 MiB 16 MiB
L2 macro 8 KiB 16 KiB, 54% larger
L2 macro density 18.3 Mbit/mm² 23.7 Mbit/mm²
L2 bank-level density 10.4 Mbit/mm² 16.9 Mbit/mm²

Source: STEEL Panther Lake teardown, September 2026

02

Advanced packaging and interconnect analysis

Sub-micron X-ray CT and laminography, cross-section, SEM

X-ray CT slices through a complete package without a cut, resolving microbumps, hybrid bonds, TSVs and substrate layers. Where a published pitch and the measured pitch differ, the part wins.

What it reveals: Die-to-die interface design, bump and TSV pitch, interposer and substrate construction, redistribution layer count, and the assembly cost and yield exposure.

X-ray CT scroll through a complete package, XZ plane
X-ray XZ slice through the I/O die-to-die interconnect: bump rows above a row of solder balls, 200 micron scale bar
I/O die-to-die interconnect, XZ slice
X-ray XY slice of the I/O die-to-die bump field and through-silicon vias, 200 micron scale bar
I/O die-to-die bump field and TSVs, XY slice
X-ray slice of a GPU die-to-die microbump array with a measured 25.9 micron pitch
GPU die-to-die microbump array, 25.9 µm local pitch
03

Transistor and cell-level benchmarking

FIB and TEM cross-sections, fin-cut and gate-cut; fin profile, library, metal-stack and bitcell measurement

Surgical precision. Fin-cut and gate-cut TEM through logic and SRAM gives pitches, cell heights, fin profiles and bitcell geometry, converted into density figures on one scale for every foundry.

What it reveals: Logic and SRAM density, the scaling boosters in use, the patterning scheme and what it costs, and how much runway a roadmap has left.

Kirin 9030 and Helio G99 fin profiles with annotated fin pitch, height and width
Fin profile, Kirin 9030 (SMIC N+3) left and Helio G99 (TSMC N6) right, fin-cut, with the measured front-end dimensions

SMIC N+3 vs TSMC N6 front end and cell

Kirin 9030 and Helio G99, TEM cross-sections through CPU logic

Dimension SMIC N+3 TSMC N6
Fin pitch 32 nm 34 nm
Fin aspect ratio ~9.5 : 1 7.8 : 1
Contacted gate pitch 57 nm 57 nm
Cell height, 2+2 fins 228 nm 240 nm
Scaling boosters COAG, SDB SDB
Logic density, Bohr 113.4 MTr/mm² 107.7 MTr/mm²

Source: STEEL SMIC N+3 teardown, June 2026

Kirin 9030 and Helio G99 lower metal layers with annotated M0 pitch and gate pitch
Lower metals M0 to M3, fin-cut, with measured pitches and the patterning each implies

SMIC N+3 vs TSMC N6 local interconnect

Measured pitches and the patterning each implies

Layer SMIC N+3 TSMC N6
M0 pitch 32.5 nm, SAQP ~40 nm, SADP
M1 pitch 38 nm, 3:2 to gate 57 nm, 1:1 to gate
M2 pitch 40 nm 40 nm
M3 pitch 44 nm 40 nm
Track height 5.7 T 6 T class
M0 vs Intel 18A as shipped 32.5 nm 36 nm

Source: STEEL SMIC N+3 teardown, June 2026

Kirin 9030 8T SRAM fin-cut TEM with alternating cell rows outlined
Kirin 9030 8T SRAM, fin-cut, HFW 1.55 µm, with measured and derived bitcell sizes

SMIC N+3 SRAM bitcells measured and derived

8T high-current cell found in the Kirin 9030 GPU; 6T cells derived from the same fin and gate grid

Cell Bitcell Peak density
8T HCC, 1:2:2-2:2, measured 0.0463 µm² 21.6 Mib/mm²
6T HCC, derived 0.0337 µm² 29.7 Mib/mm²
6T HDC, derived 0.0260 µm² 38.5 Mib/mm²
6T HCC vs Intel 3 and 4 ~12% larger
6T HDC placement near Samsung 7LPP/5LPP slightly below TSMC N7/N6
Bitcell shrink, N+2 → N+3 ~19%

Source: STEEL SMIC N+3 teardown, June 2026

6T HDC, 6T HCC and 8T HCC bitcell schematics
6T HDC, 6T HCC and 8T HCC bitcell schematics used to derive the 6T cells from the measured 8T cell

Deriving the 6T cells from the measured 8T cell

The 6T cells share the 8T cell’s fin and gate grid, so their sizes follow from the measured cell

Cell Bitcell Peak density
8T HCC, 1:2:2-2:2, measured 0.0463 µm² 21.6 Mib/mm²
6T HCC, derived 0.0337 µm² 29.7 Mib/mm²
6T HDC, derived 0.0260 µm² 38.5 Mib/mm²

Source: STEEL SMIC N+3 teardown, June 2026

04

Materials, process, and integration

STEM-EDS elemental mapping, XTEM and fin-cut cross-sections, matched cuts across foundries

Clarity on materials, processes, and integration. New and evolving materials, process steps, and integration schemes, read from delivered products and tied to scaling, power, and performance rather than spec tables.

What it reveals: Competitive benchmarking against foundries and nodes, the process beyond the PDK for the teams that design on it, and clues for the future.

Intel 18A and Samsung SF2 interconnect EDS maps for copper, tantalum, cobalt, ruthenium and cobalt/niobium
Intel 18A vs Samsung SF2 interconnect EDS maps (Cu, Ta, Co, Ru, Co/Nb) with the materials identified by layer

Intel 18A interconnect materials, by layer

EDS maps from Panther Lake P-core logic

Structure Material found
Contacts and nano-TSVs Mo-lined W
M0–M1 liner Co/Ru on Cu
M2–M4 liner Co
M5–M9 barrier Nb
Etch stop AlOₓ / SiN / AlOₓ
Gate dielectric La-doped HfO₂

Source: STEEL Panther Lake teardown, September 2026

Elemental STEM map of NMOS and PMOS gate-all-around stacks Seven-step reverse-engineered work-function metal process flow with a materials legend
Intel 18A RibbonFET elemental map at the 20 nm scale, and the work-function metal flow reverse-engineered from it
XTEM cross-section through Kirin 9030 8T SRAM with cell rows outlined Schematic comparing SADP and SAQP patterning steps
SMIC N+3 (Kirin 9030): the 8T SRAM fin-pitch sequence, with the CPU cores, pins the fin patterning to SAQP from a 128 nm mandrel

Breadth and depth, on one team.

The SemiAnalysis teardown lab is built on talent experienced in systems, architecture, fab, and lab. Expertise in sample preparation, imaging, spectroscopy, and analysis. Where the market has no tool for the job, STEEL develops its own analytical tools, methods, and software.

What only a teardown can tell you.

Datasheets and benchmarks stop at what a vendor publishes and what a workload exercises. Physical analysis measures the part itself: fab and node, packaging, process, and cost.

What datasheets, benchmarks, and the lab can each tell you
Information Datasheets Benchmarks STEEL What it decides
Fab and node verification No No Direct and detailed Export-control violations and the response to them
Architecture details General Indirect Direct and detailed Capability benchmarking
Advanced packaging specifics General No Direct and detailed Monitoring and responding to PRC advances
Process reverse engineering No No Direct and detailed IP discovery
Manufacturing cost estimation No No Detailed estimate Component costing
Custom process variations No No Direct, with advanced analysis Monitoring and responding to PRC advances
Circuit schematics, partial or full No No Direct, via extraction IP discovery

On the bench.

Recent work from the lab, and what is in the queue.

Optical microscope view of a green interposer surface with fine wiring and small pads Interposer, optical, after delayering

Apple M5 Pro and Max: Fusion architecture

Apple’s first use of TSMC’s SoIC-mH 2.5D packaging. The CPU and GPU are separate dies, hybrid-bonded copper to copper onto the interposer.

Close-up of a small blue chip with an Apple logo and part markings on its lid Apple IVR, package marking

Apple M5 Max: integrated voltage regulator

Apple’s IVR chip sits on the back of the logic board and holds a stable voltage for the CPU and GPU. Located, delidded, and cut in cross-section.

Top-down photograph of the Ascend 910C accelerator card Accelerator card, optical

Huawei Ascend 910C: advanced packaging

Polished cross-section and 2D X-ray of the full package: ABF build-up, memory-stack TSVs, and GPU microbumps, with pitches and critical dimensions measured.

Blue-tinted view of a phone logic board, two camera modules at the top and shielded blocks of components below Phone logic board

Kirin 9030 Pro: iPoP architecture

Package-on-package with an organic interposer. X-ray identified the memory substrate supplier and likely heat-management structures.

In the queue

  • Exynos 2600
  • Apple M5 series
  • Ascend 910C
  • Advanced optics products
  • Advanced networking products
  • Advanced datacenter ICs

How a device comes apart.

The same path for every device. Once the die is exposed, the four analysis branches run in parallel.

  1. 01 Non-destructive analysis X-ray, macro optical
  2. 02 Disassembly and package analysis X-ray, macro, micro
  3. 03 Decapsulation and die exposure Prep labs
  • Die imaging Prep labs, optical, SEM
  • Critical dimensions, materials characterization, fab sourcing Optical, FIB, SEM, TEM
  • Delayering and inspection Prep labs, FIB, SEM
  • Circuit extraction and cost analysis Architecture, BoMs
  • Comprehensive reporting Strategic prioritization
  • Transistor and functional-unit electrical analysis Planned

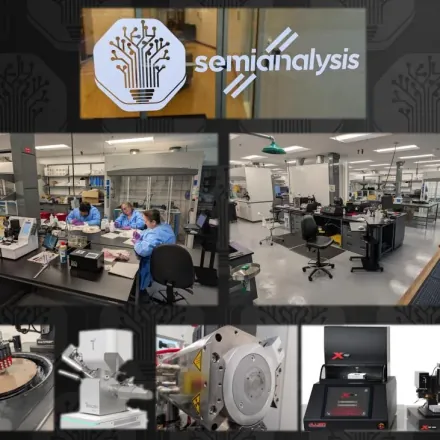
18,000 square feet in Hillsboro.

Hillsboro is the center of North American foundry manufacturing. The lab sits in the Amberglen district, on the same streets as the major semiconductor firms.

  • Full-featured preparation and analytical labs
  • More than 90 years of combined failure-analysis experience on the team
  • Room to bring new capabilities in quickly
  • Space for collaborators and affiliates

9025 NE Von Neumann Drive
Hillsboro, OR 97006
Open in Maps

Photographs from inside the STEEL lab: benches, microscopes, sample-preparation tools, and the SemiAnalysis sign at the entrance Photographs from inside the STEEL lab: benches, microscopes, sample-preparation tools, and the SemiAnalysis sign at the entrance

Talk to the lab.

To discuss teardown access, subscriptions, or a commissioned teardown, tell us what you are after. The sales team comes back with scope, timing, and pricing.

  • Access to the published teardown reports
  • Subscriptions for ongoing coverage
  • Commissioned teardowns and custom analysis

The lab is hiring product, architecture, packaging, and technician roles. See the open roles

Tell us what you are trying to find out.

← Back

Thank you for your response. ✨